Skip to content

Benchmark & method · adaptive driver alerting · CoRL 2026

VLAlertObserve Before You Alert: Adaptive Driver Alerting with Vision–Language Models

A unified per-tick benchmark for deciding when a driving system should stay SILENT, OBSERVE, or ALERT — and a vision–language policy in which the OBSERVE action acts as an internal evidence-gathering decision that delays uncertain warnings.

At each one-second tick a model sees the last eight frames and predicts the appropriate alert action. VLAlert-Bench joins six driving-event sources into one task — 13,534 videos and 192,892 labelled ticks across five splits — and the VLAlert policy, built on Qwen3-VL-4B, is scored on it and on held-out ADAS-TO-Critic takeover clips.

CoRL 2026 · accepted · arXiv 2609.08130CoRL 2026 Travel AwardCC BY 4.0 · gated, manual approval

Yuhang Wang1·Lingyao Li2·Hao Zhou1

1University of South Florida · MOTIF-Lab   2University of Arizona
demo · per-tick decision · 1 HzSILENT → OBSERVE → ALERT

The paper's abstract describes VLAlert-Bench as built from four real-world dashcam alert datasets; the released card adds the ADAS-TO-Critic and Kaggle ACCIDENT extra splits, bringing the sources to six.

01 · OVERVIEW

When is the evidence enough to warn?

The arXiv abstract, verbatim, beside what you need to know at a glance.

Driver alerting from dashcam video requires sequential decision-making under partial observability: a system must decide not only whether a scene is risky, but also when the evidence is sufficient to warn. Most existing accident anticipation models output a binary risk score, leaving ambiguous scenes to be handled by thresholding. We propose VLAlert, a vision-language alerting framework that casts warning generation as a tri-action policy over SILENT, OBSERVE, and ALERT. The OBSERVE action acts as an internal evidence-gathering decision that delays uncertain warnings and changes the next observation window, creating a lightweight perception-action loop for adaptive alerting. VLAlert uses Qwen3-VL-4B as a safety-evidence generator and pools hidden states from structured belief spans to form compact representations for danger estimation and policy prediction. We evaluate VLAlert on VLAlert-Bench, a unified per-tick benchmark from four real-world dashcam alert datasets, and further test transfer to held-out naturalistic ADAS takeover clips. On VLAlert-Bench validation, VLAlert achieves the highest deployment-oriented utility among tested baselines, with DAUS 0.4878 compared with 0.4752 for Open-BADAS, and improves AUROC, AP_tick, F1_t, and balanced accuracy from 0.610, 0.176, 0.276, and 0.581 to 0.689, 0.195, 0.297, and 0.648, respectively. On 221 held-out ADAS-TO-Critic clips, VLAlert improves R@5s from 74.2% to 88.7% and F1 from 0.585 to 0.686. These results indicate that adaptive observation and safety-focused VLM representations provide measurable gains for driver-facing alert decisions.

02 · DEMOS

Per-tick decisions on real driving-event footage

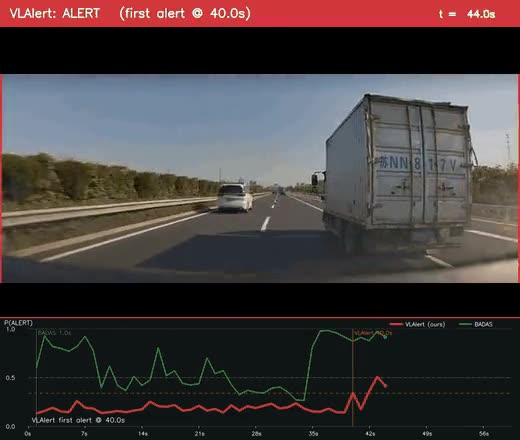
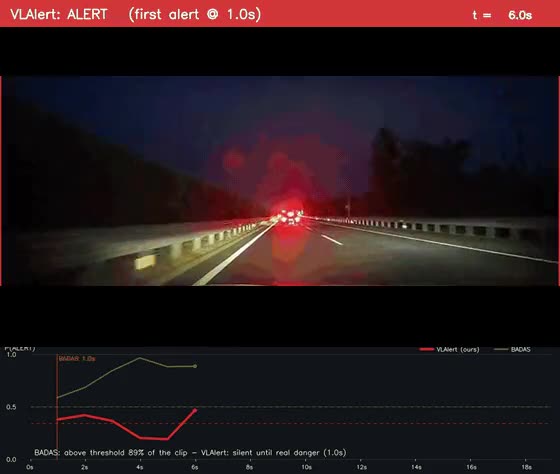
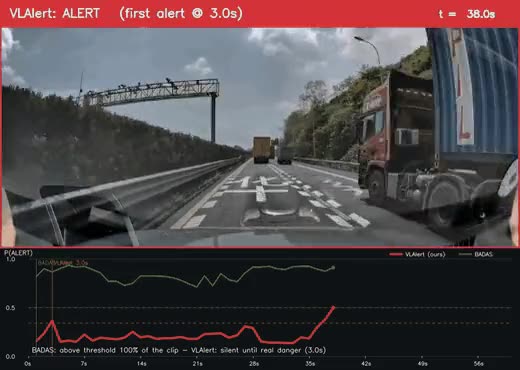
Each clip overlays the VLAlert decision (header) and the alert probability trace of VLAlert against the BADAS baseline (bottom). Red marks the earliest ALERT.

Per-tick alert decision
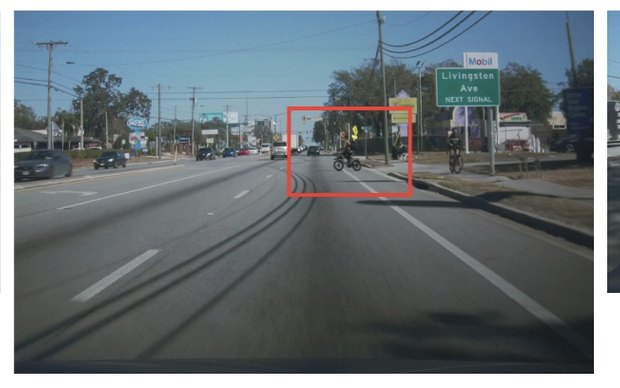
Per-tick alert decision. Alert decision on an approaching hazard: the policy stays SILENT until the risk builds, then alerts.
OBSERVE → ALERT escalation
OBSERVE → ALERT escalation. Escalation from OBSERVE to ALERT on a night-time highway scene.
Hazard-driven ALERT
Hazard-driven ALERT. A safety-critical collision sequence; the red header marks the earliest alert.
03 · EVIDENCE

What the numbers rest on

0.4878 DAUS · Open-BADAS 0.4752

Deployment-oriented utility is where the tri-action policy pays off.

On VLAlert-Bench validation, VLAlert achieves the highest deployment-oriented utility among tested baselines — DAUS 0.4878 against 0.4752 for Open-BADAS; DAUS scores the usefulness of the alert stream rather than frame-level accuracy alone.

.689 AUROC · from .610

Four frame-level metrics move together.

AUROC .610 → .689, APtick .176 → .195, F1t .276 → .297, balanced accuracy .581 → .648.

88.7 % R@5s · from 74.2 %

It transfers to the lab's own takeover clips.

On 221 held-out ADAS-TO-Critic clips — naturalistic Level-2 takeovers recorded by the lab, not web uploads — recall within five seconds rises from 74.2 % to 88.7 % and F1 from .585 to .686.

192,892 ticks · five splits · six sources

One per-tick task over six event datasets.

A tick is a 1-second sliding-window record carrying 8 consecutive frame indices plus the action label at the window's last frame. The two extra splits — ADAS-TO (lab-recorded takeovers) and the Kaggle ACCIDENT challenge — are held out of training.

Split table in the results section.
04 · METHOD

A perception–action loop with an OBSERVE action

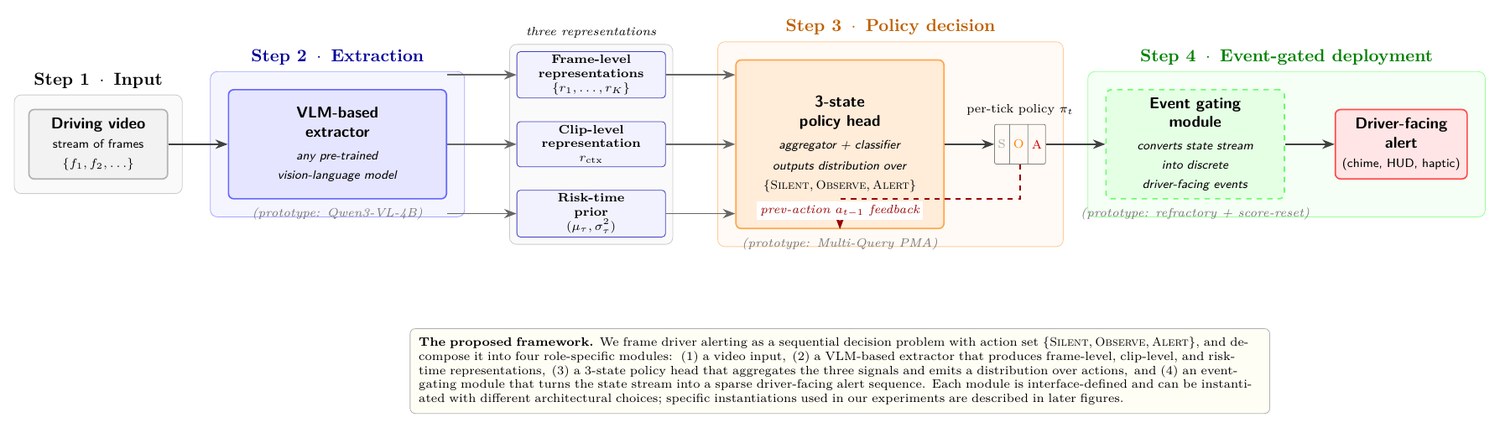
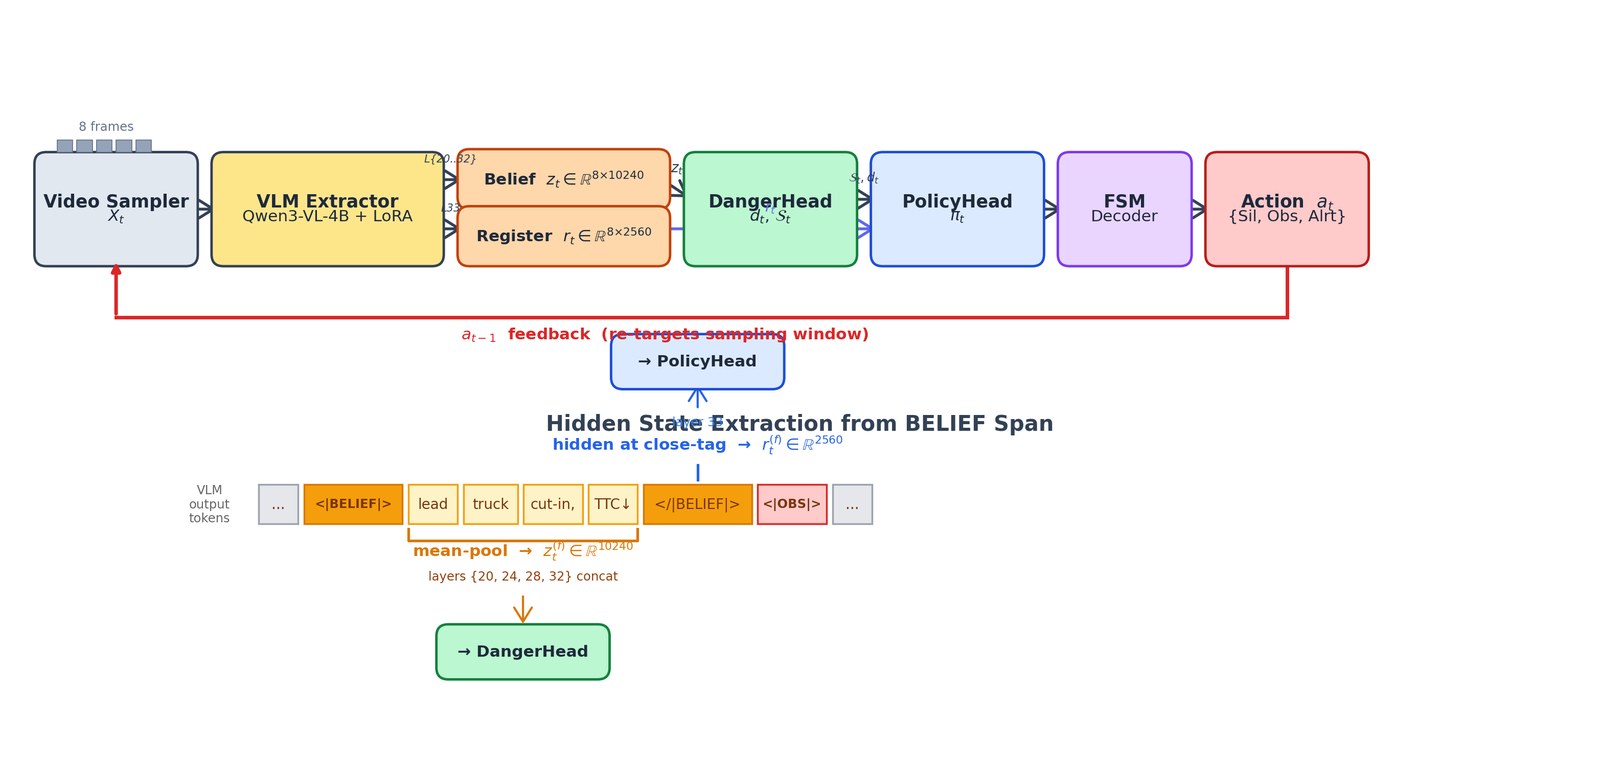
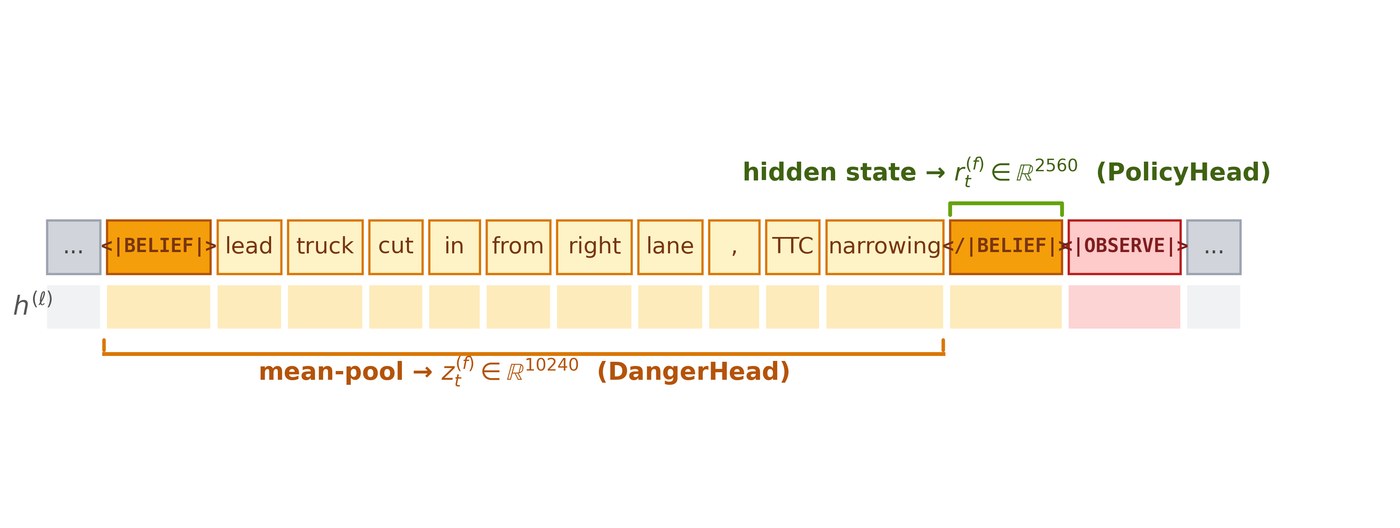
VLAlert uses Qwen3-VL-4B as a safety-evidence generator and pools hidden states from structured belief spans to form compact representations for danger estimation and policy prediction.

The VLAlert pipeline: a per-tick tri-action policy with an OBSERVE action that delays uncertain warnings and changes the next observation window.
Model architecture for per-tick alert decisions.
Belief spans over the SILENT / OBSERVE / ALERT states.
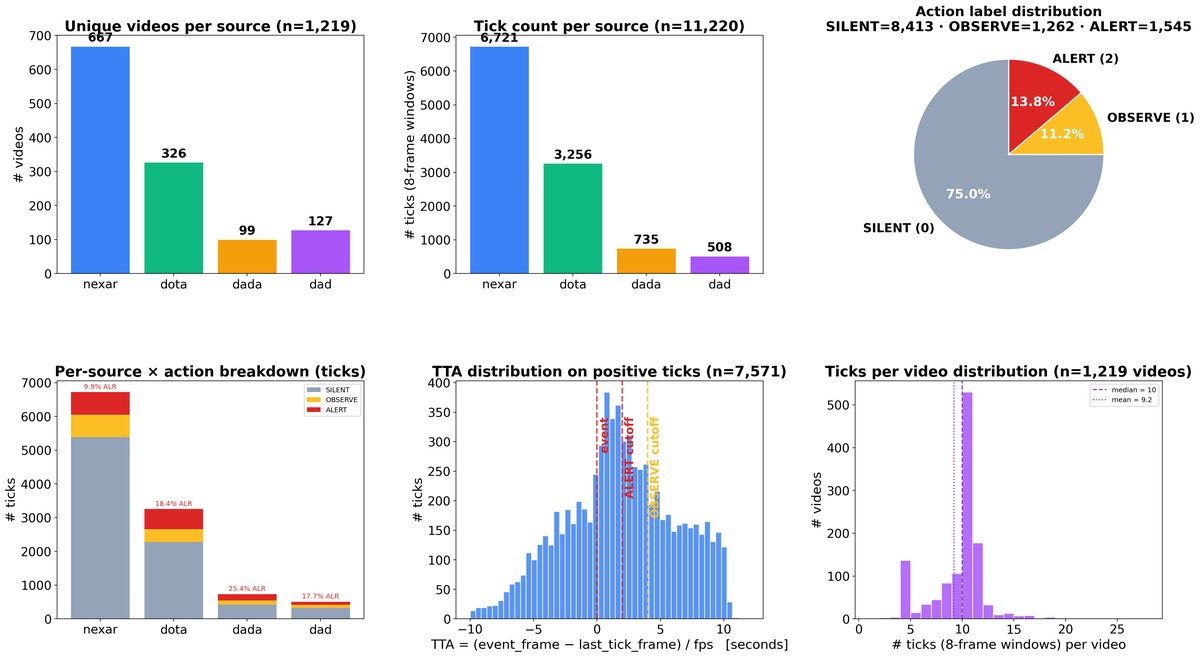
Label distribution across the validation splits.
05 · RESULTS

Tables, baseline first

VLAlert-Bench validation · values as reported in the arXiv v1 abstract

MetricReferenceVLAlert
DAUS (deployment-oriented utility)Open-BADAS 0.47520.4878
AUROC0.6100.689
APtick0.1760.195
F1t0.2760.297
Balanced accuracy0.5810.648

The abstract names Open-BADAS for the DAUS comparison; the other reference values are quoted as the abstract gives them ("from … to …"). Full tables are in the paper.

Label distribution across the validation splits
Label distribution across the validation splits.
Sources & notes
    06 · DATA & ACCESS

    Get the benchmark

    On request

    VLAlert-Bench

    13,534 videos across five splits, 192,892 one-second labelled ticks, per-frame action labels and split manifests; the ADAS-TO-Critic mp4 corpus is hosted directly. Gated, manual approval: request access with an institutional email and your intended use.

    License: CC BY 4.0 for the benchmark annotations and manifests; the source videos keep their original datasets' terms.

    Open

    Paper

    Observe Before You Alert: Adaptive Driver Alerting with Vision–Language Models — CoRL 2026; arXiv 2609.08130 (v1, 8 Sep 2026).

    Not listed

    Model weights & code

    No code or checkpoint release is listed on the dataset card as of October 2026. Contact the authors for the policy model.

    07 · CITE

    Read the paper, cite the benchmark

    BibTeX
    @inproceedings{wang2026vlalert,
      title     = {Observe Before You Alert: Adaptive Driver Alerting with Vision–Language Models},
      author    = {Wang, Yuhang and Li, Lingyao and Zhou, Hao},
      booktitle = {Conference on Robot Learning (CoRL)},
      year      = {2026},
      url       = {https://arxiv.org/abs/2609.08130}
    }

    Related work from the lab

    Visitors